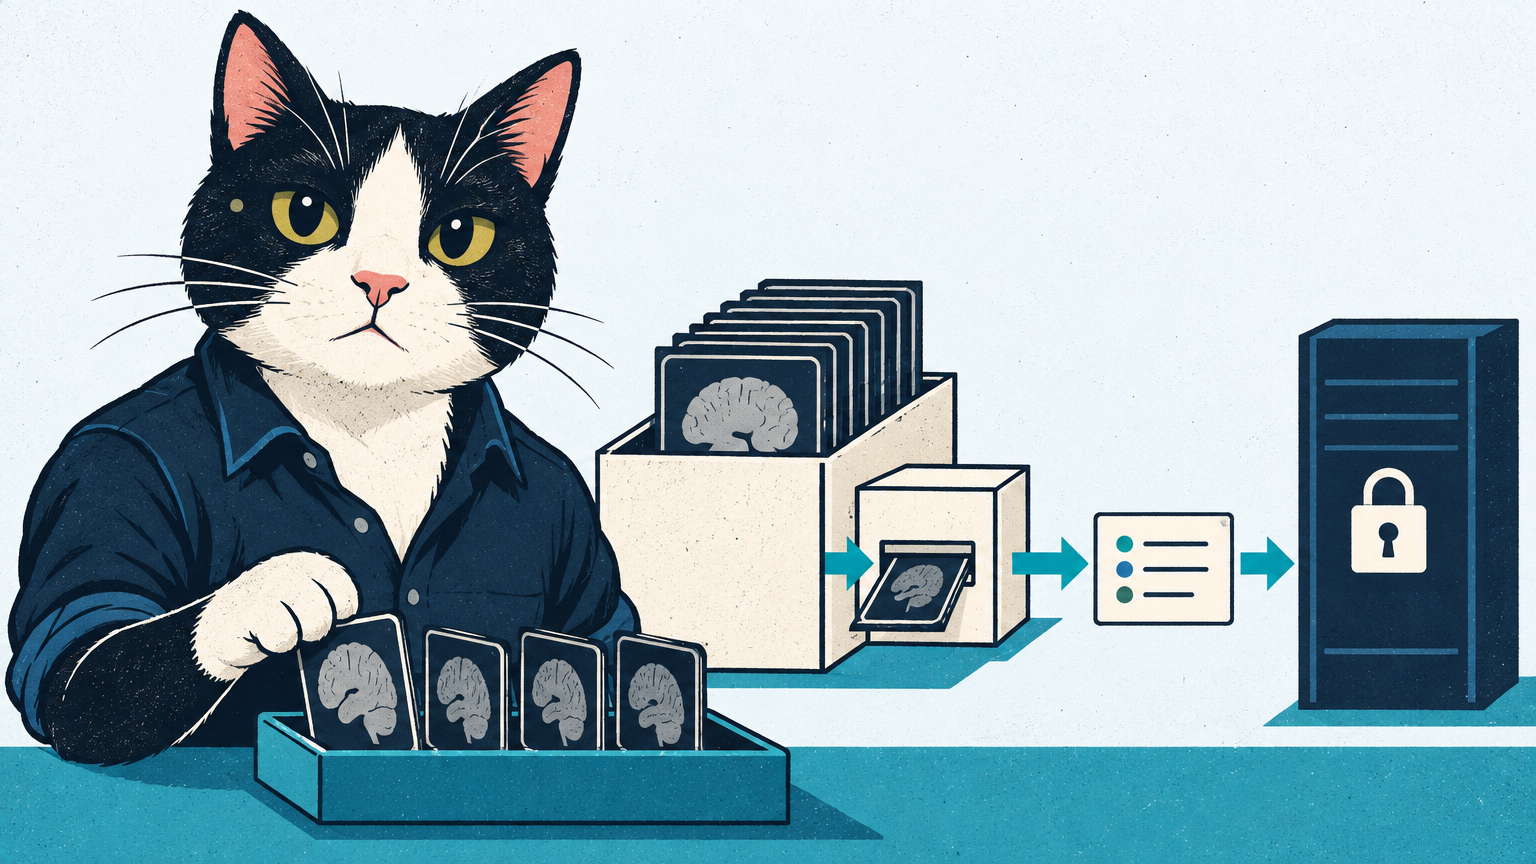
[!NOTE] TL;DR Keep raw BIDS runs immutable and inspect each volume through NiBabel's array proxy. Record the four discarded scans and preserve event timing before producing derivatives. Expose a gated manifest through Django, not a public NIfTI download.
A run that outgrew the notebook
My fMRI data pipeline started with a deceptively obedient MATLAB script. The script behaved. My laptop fan filed an objection. In one study, each functional run contained 952-1145 volumes, and I discarded the first four before modeling the signal. That range came from my 2024 neuroimaging work, not a synthetic load test. An analyst can remember those four volumes; an API cannot.
My main question was how to carry that acquisition history into a bounded-memory research service without treating a pseudonym as a privacy exemption. The question reaches beyond imaging. EEG samples and behavioral responses need the same temporal anchor, even when their storage formats differ.
The missing contract
One spontaneously imagines that converting a MATLAB notebook into an endpoint is mostly a matter of wrapping a function. The numbers say otherwise: four discarded volumes at TR = 2.2 s shift the start of the retained series by 8.8 s. If you silently reuse event onsets against that trimmed series, you can misalign your design matrix. Keeping the original events unchanged is correct for the original raw run. A derivative with a new time origin needs an explicit transformation.
My study used SPM12 to correct motion and slice acquisition delays, then normalized images to a standard space. The original analysis also used an 8 mm smoothing kernel. Those choices are scientifically substantive; my proposed service does not recreate them. It inspects raw input and records what a downstream processing job must know.
The BIDS common principles distinguish raw data from derivatives and require separate storage for the latter. That boundary is useful. A sub-01_task-memory_bold.nii.gz file may have a valid-looking name while its event clock, sidecar metadata or provenance is wrong. A filename is not a validation report.
| Stage | Notebook habit | Service contract |
|---|---|---|
| Input | Choose a path manually | Resolve a restricted BIDS label inside a private root |
| Time | Drop four scans in a script | Record four scans and the original TR separately |
| Output | Save a result nearby | Version the derivative and publish only approved metadata |
A private architecture
Here I present VAST, a reference design for Volume Audit and Study Trace. I did not deploy VAST on the 2024 imaging cohort. I derived its run boundary from that study and its API boundary from a separate research platform where I used Django and Django Ninja for scientific collection and exports. Conflating those systems would make a very tidy architecture diagram and a false account of what ran.
flowchart LR
    A[Restricted BIDS raw dataset] --> B[Offline VAST worker]
    B --> C[Private run manifest]
    B --> D[Quarantine for invalid runs]
    C --> E[PostgreSQL access catalogue]
    E --> F[Django research API]
    G[Authorised researcher] --> F
    F --> H[Approved metadata only]
    C --> I[Versioned derivative job]
The raw store is read-only for the worker. The worker checks one named run, computes a file digest and emits a small manifest; a separate process validates BIDS metadata and checks the sidecars. Only then does a curator approve its catalogue entry. I keep imaging payloads out of ordinary API responses. An authenticated request still needs study-scoped authorization and an access log.
In my separate research web application, the declared dependency constraints included Django ^5.1.2 and Django Ninja ^1.3.0. That is evidence for the interface choice, not evidence that fMRI images were served by it. For new uploads, Django 5.2's upload documentation describes a 2.5 MB default memory threshold and recommends chunks() over read(). I would land uploads in a controlled staging area, never accept an arbitrary filesystem path from the browser, and keep parsing outside the request transaction.
VAST's bounded reader
I wrote the following as a reproducible inspection component, not a replacement for SPM12 or a BIDS validator. It targets Python 3.11 and Pydantic v2, with numpy and nibabel installed. Save it as inspect_bold.py, then run python inspect_bold.py /private/bids 01 memory against a pre-curated dataset. The labels are validated before path construction. The root itself must be a trusted configuration value, never a request parameter.
from __future__ import annotations
import hashlib
import re
import sys
from pathlib import Path
import nibabel as nib
import numpy as np
from pydantic import BaseModel, ConfigDict, Field, computed_field, field_validator, model_validator
class RunSpec(BaseModel):
    model_config = ConfigDict(strict=True)
    root: Path = Field(..., description="Trusted private BIDS root.")
    subject: str = Field(..., description="BIDS subject label without sub-.")
    task: str = Field(..., description="BIDS task label without task-.")
    @field_validator("subject", "task")
    @classmethod
    def safe_label(cls, value: str) -> str:
        if re.fullmatch(r"[A-Za-z0-9]+", value) is None:
            raise ValueError("BIDS label must be alphanumeric")
        return value
    @computed_field
    @property
    def image_path(self) -> Path:
        name = f"sub-{self.subject}_task-{self.task}_bold.nii.gz"
        return self.root / f"sub-{self.subject}" / "func" / name
class RunManifest(BaseModel):
    model_config = ConfigDict(strict=True)
    subject: str = Field(..., description="Validated subject label.")
    task: str = Field(..., description="Validated task label.")
    shape: tuple[int, int, int, int] = Field(..., description="Voxel grid and volume count.")
    discarded: int = Field(..., ge=0, description="Discarded initial volumes.")
    nonfinite_volumes: int = Field(..., ge=0, description="Volumes containing nonfinite values after discard.")
    sha256: str = Field(..., min_length=64, max_length=64, description="Digest of input file bytes.")
    @computed_field
    @property
    def retained_volumes(self) -> int:
        return self.shape[3] - self.discarded
    @model_validator(mode="after")
    def check_counts(self) -> RunManifest:
        if any(size <= 0 for size in self.shape) or self.retained_volumes <= 0:
            raise ValueError("invalid image shape or discard count")
        if self.nonfinite_volumes > self.retained_volumes:
            raise ValueError("nonfinite count exceeds retained volumes")
        return self
def inspect(spec: RunSpec) -> RunManifest:
    path = spec.image_path
    if not path.is_file():
        raise FileNotFoundError(path)
    image = nib.load(str(path))
    if len(image.shape) != 4 or image.shape[3] <= 4:
        raise ValueError("expected a 4D BOLD run with more than four volumes")
    digest = hashlib.sha256()
    with path.open("rb") as handle:
        for block in iter(lambda: handle.read(1024 * 1024), b""):
            digest.update(block)
    nonfinite = 0
    for index in range(4, image.shape[3]):
        # Slicing the proxy avoids retaining the complete 4D image.
        volume = np.asarray(image.dataobj[..., index], dtype=np.float32)
        nonfinite += int(not np.isfinite(volume).all())
    return RunManifest(subject=spec.subject, task=spec.task, shape=tuple(image.shape), discarded=4, nonfinite_volumes=nonfinite, sha256=digest.hexdigest())
if __name__ == "__main__":
    if len(sys.argv) != 4:
        raise SystemExit("usage: python inspect_bold.py ROOT SUBJECT TASK")
    spec = RunSpec(root=Path(sys.argv[1]), subject=sys.argv[2], task=sys.argv[3])
    print(inspect(spec).model_dump_json())
The Pydantic documentation describes strict validation and typed models; these checks reject malformed labels and inconsistent counts. They do not validate a whole BIDS dataset. The digest identifies a particular file byte stream, not a person or a consent state. Keep it in a restricted manifest.
NiBabel's memory guide explains the relevant trap: get_fdata() normally fills an image-level cache, while dataobj[..., index] reads a slice without materializing the entire array. A compressed .nii.gz can still incur substantial decompression work for repeated slices. The worker is bounded by a volume-sized working array and library buffers, not guaranteed to finish quickly.
Results without a stopwatch
I have not benchmarked VAST. I can report the measured run-length range from my 2024 study and derive storage arithmetic for an assumed, not observed, 64 x 64 x 40 spatial grid. That grid contains 163,840 voxels per volume. At 4 bytes per voxel, one float32 volume is 0.625 MiB. At 8 bytes per voxel, a fully materialized float64 run spans 1190-1431.25 MiB before processing intermediates. Neither figure is a measured peak RSS.
{
  "type": "bar",
  "data": {
    "labels": ["952 volumes", "1145 volumes"],
    "datasets": [
      { "label": "Estimated full float64 array, MiB", "data": [1190, 1431.25], "backgroundColor": ["#3b82f6", "#3b82f6"] },
      { "label": "One float32 volume, MiB", "data": [0.625, 0.625], "backgroundColor": ["#f59e0b", "#f59e0b"] }
    ]
  },
  "options": {
    "responsive": true,
    "plugins": { "title": { "display": true, "text": "Derived array sizes, assumed 64 x 64 x 40 grid; not a benchmark" } },
    "scales": { "y": { "title": { "display": true, "text": "MiB" } } }
  }
}
The comparison is deliberately asymmetric: one bar is an entire run, the other is one processing slice. It illustrates an allocation decision, not an end-to-end throughput claim. With four volumes removed, the observed endpoint counts become 948 and 1141 retained volumes. The range between those endpoints comes from different runs, not repeated timing trials with a standard deviation.
I call the remaining risk the amputated clock. Picture a railway timetable after someone tears off its first page. Every later train remains on the track, but a reader who resets the station clock changes what each arrival means. The same error occurs when a trimmed BOLD series inherits unadjusted event onsets without a declared time origin.
Limits, consent and the next test
Although the proxy prevents an eager 4D array allocation, my design does not guarantee low wall-clock time for gzip-backed files. Nor does a nonfinite_volumes count detect motion artifacts, wrong slice timing or an erroneous spatial transform. I would test peak RSS and elapsed time across .nii and .nii.gz, then compare sampled values and event alignment against the original SPM12 analysis. Those measurements remain to be done.
VAST's example accepts one simple subject/task filename. Real BIDS datasets may include sessions, runs and inherited JSON metadata; they need a proper validator and explicit dataset selection. The inspection code does not process EEG or behavioral TSVs. Their sampling frequencies, clocks and missing-value semantics require separate typed readers, linked to the same study-level provenance record.
Privacy is a separate gate. The European Data Protection Board's health research clarification distinguishes pseudonymisation from anonymisation and requires an Article 6 basis alongside an Article 9 condition for health-data processing. It also warns against reducing a DPIA decision to dataset size alone. Before any deployment, I would ask the controller and DPO to establish purpose, lawful grounds, retention, access policy and whether a DPIA is required. An encrypted bucket cannot make that decision for you.
Beyond the scanner
More generally, a scientific pipeline earns trust when it preserves the path from signal to decision, including the inconvenient four scans. You can find related engineering work in the blog or talk to me about a research platform. The laptop fan can retire.